Which one should you use?
Both toolkits produce good pseudo-random numbers. The choice is about what you do with them.
| Use | When |
|---|---|
| random | One number at a time, picking from lists, games, small scripts. Built into Python, no install needed. |
| numpy | Arrays of numbers, statistics, simulations, machine learning, data science. Much faster for large amounts. |
| secrets | Passwords, tokens, PINs and anything that must be unpredictable. Built in, cryptographically secure. |
A rule of thumb: if the result goes into a list or a print statement, use random. If it goes into an array, a DataFrame or a plot, use NumPy. If someone could profit from guessing it, use secrets.
random.randint: a random whole number
Import the module once and call randint with the lowest and highest value you want:
import random

roll = random.randint(1, 6)         # 1, 2, 3, 4, 5 or 6
pin = random.randint(1000, 9999)    # a four-digit number
print(roll, pin)
The important detail: randint(a, b) includes both ends, so randint(1, 6) really can return 6. It is the only function in this guide that works that way, and the reason for the most common bug in Python random code, covered further down.
Its cousin random.randrange(start, stop, step) follows the same rule as range(): the stop value is excluded. That makes it handy for steps, such as random.randrange(0, 101, 5) for a multiple of 5 from 0 to 100, or random.randrange(1, 100, 2) for an odd number.
Random decimals: random() and uniform()
random.random() returns a float from 0.0 up to, but not including, 1.0. Everything else in the module is built on it. For a decimal in your own range, use random.uniform(a, b):
import random

random.random()                  # e.g. 0.6394267984578837
random.uniform(1.5, 4.5)         # e.g. 3.0821...
round(random.uniform(5, 50), 2)  # a price like 23.17
If you need values that cluster around an average instead of spreading evenly, such as heights or test scores, use random.gauss(mu, sigma). For example, random.gauss(170, 10) gives heights around 170 cm, with most values between 160 and 180.
random.choice, choices and sample: picking from a list
These three functions answer the question "which item?" rather than "which number?" They look similar but behave very differently.
import random

names = ["Ana", "Ben", "Chen", "Dara", "Eli"]

random.choice(names)                  # one item, e.g. 'Chen'
random.choices(names, k=3)            # three picks, repeats allowed
random.sample(names, k=3)             # three different items

# Weighted: 'common' comes up about 7 times in 10
random.choices(["common", "rare", "epic"], weights=[70, 25, 5], k=10)choicereturns a single item. It raisesIndexErrorif the list is empty, so check first if that can happen.choicespicks with replacement: the same item can come up several times. It is the only one of the three that supportsweights.samplepicks without replacement: every item appears at most once. Asking for more items than the list has raisesValueError.
random.sample is also the cleanest way to get unique random numbers. random.sample(range(1, 50), 6) draws six different numbers from 1 to 49, like a lottery ticket, without ever building a full list in memory. Since Python 3.11 sample no longer accepts a set; convert it with sorted(my_set) first.
random.shuffle: put a list in random order
random.shuffle rearranges a list in place and returns None. That second part catches people out:
import random

cards = list(range(1, 11))
random.shuffle(cards)        # cards is now shuffled
print(cards)

shuffled = random.shuffle(cards)
print(shuffled)              # None! shuffle doesn't return the list

# Keep the original and get a shuffled copy instead
copy = random.sample(cards, k=len(cards))
Shuffle only works on mutable sequences such as lists. To shuffle a string or a tuple, turn it into a list, shuffle it and join it back, or use the random.sample trick above. If you just want to shuffle lines of text without writing code, our Word Shuffler does it in the browser.
Seeds: getting the same random numbers again
Python's generator is pseudo-random: it starts from a value called the seed and produces a fixed sequence from it. Normally the seed comes from the operating system, so every run is different. Setting it yourself makes runs repeatable, which is what you want in tests, tutorials and experiments you need to reproduce.
import random

random.seed(42)
print(random.randint(1, 100), random.randint(1, 100))

random.seed(42)
print(random.randint(1, 100), random.randint(1, 100))  # same two numbers
If you don't want to touch the global state, for example inside a library, create your own generator with rng = random.Random(42) and call rng.randint(...) on it. Each Random object keeps its own sequence.
NumPy: the modern way with default_rng
Since NumPy 1.17 the recommended API is a Generator object created with np.random.default_rng(). It is faster, has better statistical properties (it uses the PCG64 algorithm), and keeps its state to itself instead of sharing one global generator across your whole program.
import numpy as np

rng = np.random.default_rng(seed=42)    # omit the seed for fresh numbers each run

rng.integers(1, 7, size=10)             # ten dice rolls, 1 to 6
rng.random(5)                           # five floats in [0, 1)
rng.uniform(10, 20, size=3)             # three floats between 10 and 20
rng.normal(loc=0, scale=1, size=1000)   # 1,000 values from a bell curve
rng.choice(["a", "b", "c"], size=5)     # random picks from a list
Every method takes a size, which can be a number or a shape such as (3, 4) for a 3 by 4 array. Generating a million values this way takes milliseconds, while a Python loop calling random.randint a million times takes far longer.
np.random.choice: sampling with and without replacement
choice is the NumPy function people search for most, because it covers several jobs at once: random picks, unique samples and weighted draws.
import numpy as np

rng = np.random.default_rng()

rng.choice(10, size=3)                        # 3 numbers from 0..9, repeats allowed
rng.choice(np.arange(1, 50), 6, replace=False)  # 6 unique numbers from 1..49
rng.choice(["red", "green", "blue"], size=8, p=[0.5, 0.3, 0.2])  # weighted
Passing an integer n means "choose from 0 to n-1". With replace=False, asking for more items than exist raises ValueError. The probabilities in p must add up to exactly 1; if you have raw weights like 5, 3 and 2, divide them by their sum first. The legacy np.random.choice(a, size, replace, p) takes the same arguments.
np.random.normal and np.random.uniform
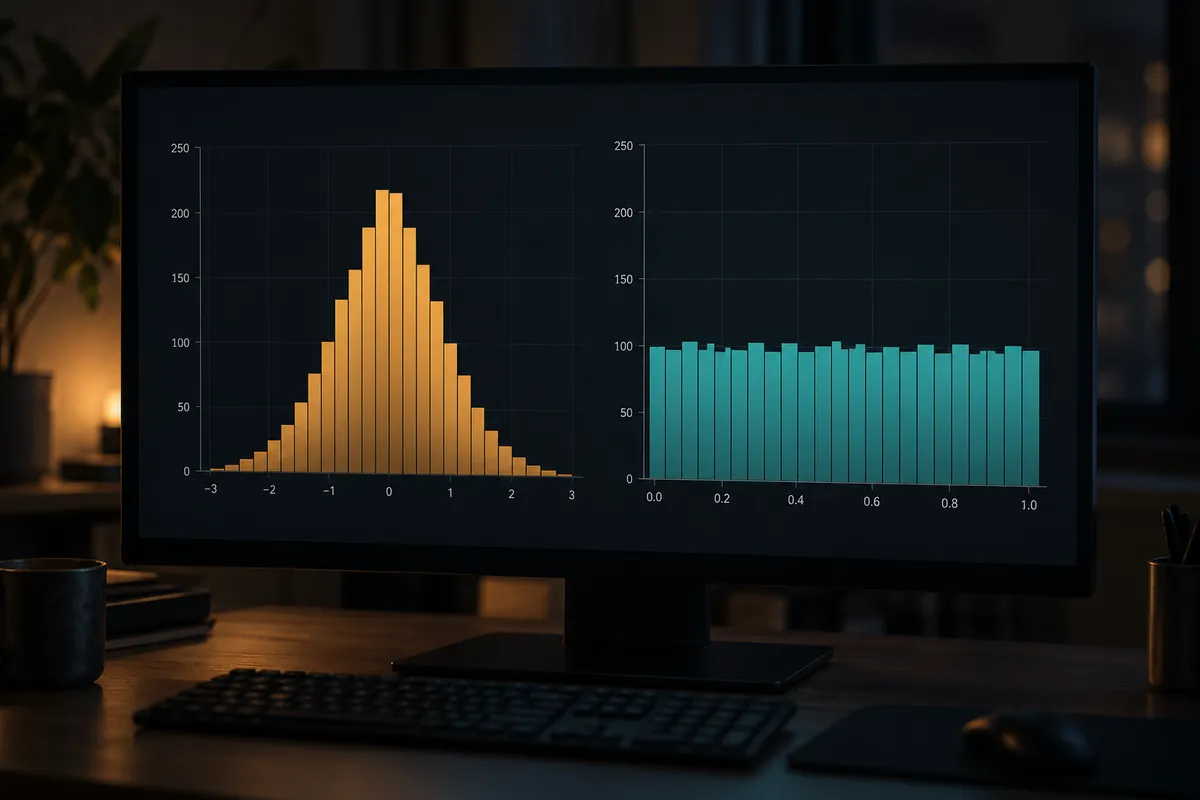
These two cover most simulation work. normal(loc, scale, size) draws from a bell curve: loc is the mean and scale the standard deviation. uniform(low, high, size) spreads values evenly from low up to, but not including, high.
import numpy as np

rng = np.random.default_rng(7)

scores = rng.normal(loc=70, scale=12, size=500)   # exam scores around 70
scores = np.clip(scores, 0, 100).round()          # keep them between 0 and 100

prices = rng.uniform(5, 50, size=200).round(2)    # prices between 5 and 50
print(scores.mean(), prices.min(), prices.max())
About 68% of normal values fall within one standard deviation of the mean, and about 95% within two. Values outside that range are rare but possible, which is why the example clips scores into 0 to 100. Other distributions work the same way: rng.poisson, rng.exponential, rng.binomial and many more.
Legacy np.random functions and their modern equivalents
Most tutorials and Stack Overflow answers still use the older functions like np.random.rand and np.random.randint. They are not going away and they still work, but NumPy no longer develops them. Here is how they translate:
| Legacy call | Modern equivalent | Note |
|---|---|---|
| np.random.seed(42) | rng = np.random.default_rng(42) | The legacy seed is global and affects all code using np.random. |
| np.random.rand(3, 2) | rng.random((3, 2)) | Floats in [0, 1). rand takes dimensions, not a tuple. |
| np.random.randn(5) | rng.standard_normal(5) | Mean 0, standard deviation 1. |
| np.random.randint(1, 7, 10) | rng.integers(1, 7, 10) | High value excluded in both. |
| np.random.random(5) | rng.random(5) | Same as random_sample. |
| np.random.uniform(0, 1, 5) | rng.uniform(0, 1, 5) | Same arguments. |
| np.random.normal(0, 1, 5) | rng.normal(0, 1, 5) | Same arguments. |
| np.random.choice(a, 3) | rng.choice(a, 3) | Same arguments. |
| np.random.shuffle(arr) | rng.shuffle(arr) | In place; rng.permutation(arr) returns a copy. |
Don't mix the two styles in one project. Setting np.random.seed(42) has no effect on a Generator you created with default_rng, so code that mixes them looks reproducible but isn't.
Two off-by-one traps
Python's random functions disagree about whether the upper limit is included. Mixing them up is the single most common bug in random code, and it is silent: nothing crashes, one value just never appears.
| Function | Upper limit | 1 to 6 is written as |
|---|---|---|
| random.randint(a, b) | Included | random.randint(1, 6) |
| random.randrange(a, b) | Excluded | random.randrange(1, 7) |
| np.random.randint(a, b) | Excluded | np.random.randint(1, 7) |
| rng.integers(a, b) | Excluded by default | rng.integers(1, 7) or rng.integers(1, 6, endpoint=True) |
So random.randint(1, 6) and np.random.randint(1, 6) look identical but do different things: the NumPy version never returns 6. When results look slightly off, such as a die that never rolls a six, check this first.
When random isn't safe: the secrets module
Both random and NumPy use generators designed for speed and statistical quality, not secrecy. With enough output, the state of Python's Mersenne Twister can be reconstructed and its future numbers predicted. That is irrelevant for a dice game and a real problem for a password reset token.
import secrets

secrets.randbelow(1_000_000)        # a number from 0 to 999,999
secrets.choice(["rock", "paper", "scissors"])
secrets.token_hex(16)               # 32 hex characters, e.g. for an API key
secrets.token_urlsafe(16)           # a URL-safe token for reset links
Use secrets for passwords, PINs, tokens, invite codes and anything else that protects access. If you need a strong password without writing code, our Password Generator uses the browser's cryptographic generator, which plays the same role as secrets, and never sends the result anywhere.
Quick answers from the command line
Python 3.13 added a small command-line interface to the random module. python -m random 6 prints a random whole number from 1 to 6, python -m random 2.5 prints a random float up to 2.5, and python -m random heads tails picks one of the words. It is handy for a quick decision in the terminal.
For anything you want to see, share or keep, such as raffle numbers, a coin flip or a set of unique numbers, a browser tool is faster still. And if your data lives in a spreadsheet rather than a script, our guide to the Excel random number generator covers RAND, RANDBETWEEN and no-repeat draws in Excel and Google Sheets.
Frequently asked questions
How do I generate a random number in Python?
random.randint(1, 10) for a whole number from 1 to 10, with both ends included. Use random.random() for a float between 0 and 1, or random.uniform(a, b) for a float in your own range.What is the difference between random.randint and np.random.randint?
random.randint(a, b) includes b, while np.random.randint(a, b) excludes it. A die roll is random.randint(1, 6) in plain Python but np.random.randint(1, 7) in NumPy.How do I get random numbers without repeats in Python?
random.sample(range(1, 50), 6) for six unique numbers from 1 to 49. In NumPy, use rng.choice(np.arange(1, 50), 6, replace=False).Should I use np.random.seed or default_rng?
np.random.default_rng(seed) for new code. It gives each part of your program its own generator, uses the newer PCG64 algorithm and is what the NumPy documentation recommends. np.random.seed still works but sets one global state for all legacy calls.Is Python's random module truly random?
secrets module for passwords and security tokens.How do I shuffle a list in Python?
random.shuffle(my_list). It shuffles the list in place and returns None. To keep the original, use random.sample(my_list, k=len(my_list)), which returns a new shuffled list.